Jean-Benoit Delbrouck / Research blog

Research blog

Long-form reading notes on radiology AI papers, with a focus on report generation.

Radiology report generationNature Medicine 2026Main6 Oct 2026~9 min read

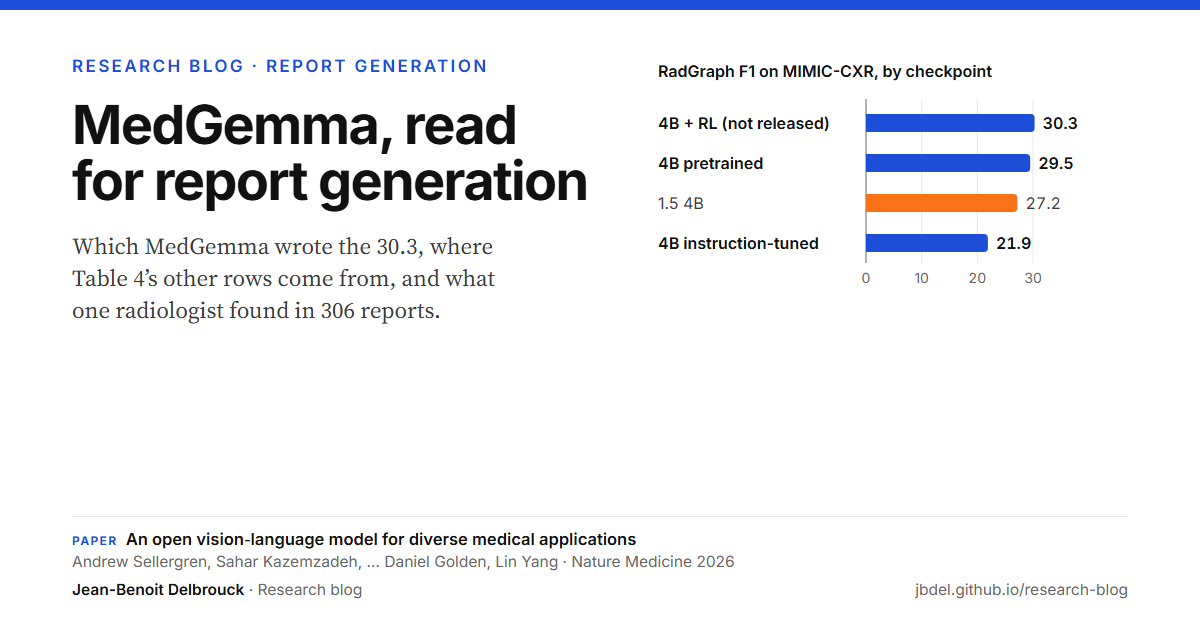
MedGemma, read for report generation

MedGemma, Google's open medical vision-language model, writes chest X-ray reports; its best RadGraph F1 in Nature Medicine is 30.3. Where that number comes from, what the comparison rows were measured on, and what the reader study shows.
CT report generationarXiv 2026Main28 Sep 2026~12 min read

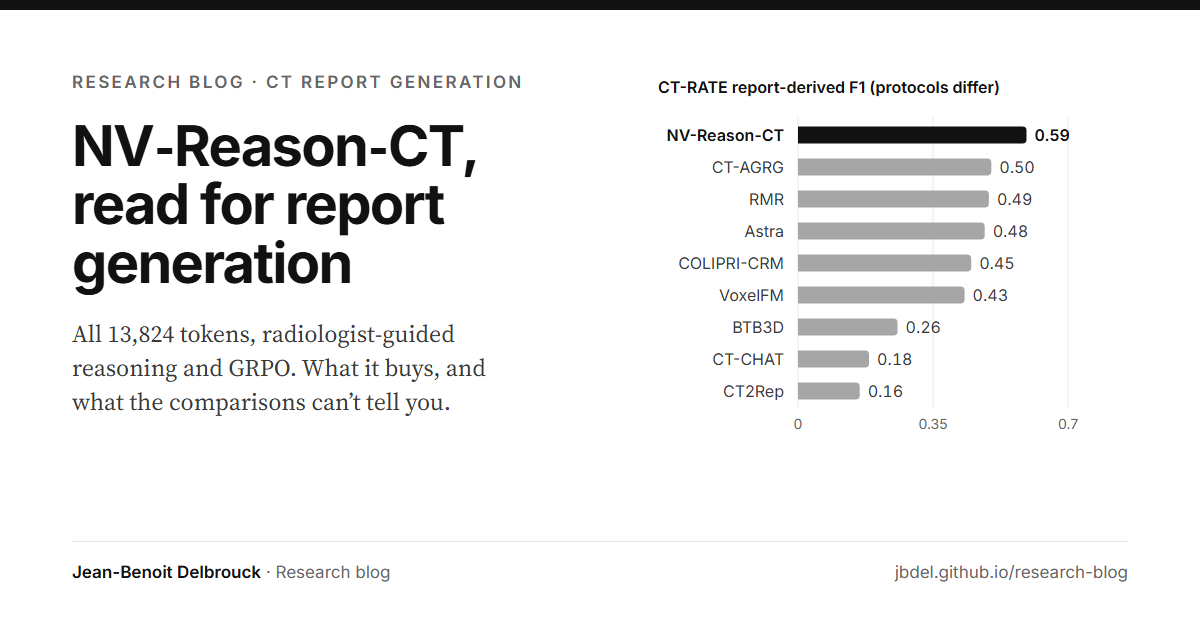
NV-Reason-CT, read for report generation

The report-generation side of NVIDIA’s NV-Reason-CT: all 13,824 visual tokens, radiologist-guided reasoning data and GRPO on finding lists, and what its CT-RATE, Merlin and RAD-ChestCT comparisons can and can’t support.

CT report generationarXiv 2026Main25 Sep 2026~15 min read

nnFoundation, read for report generation

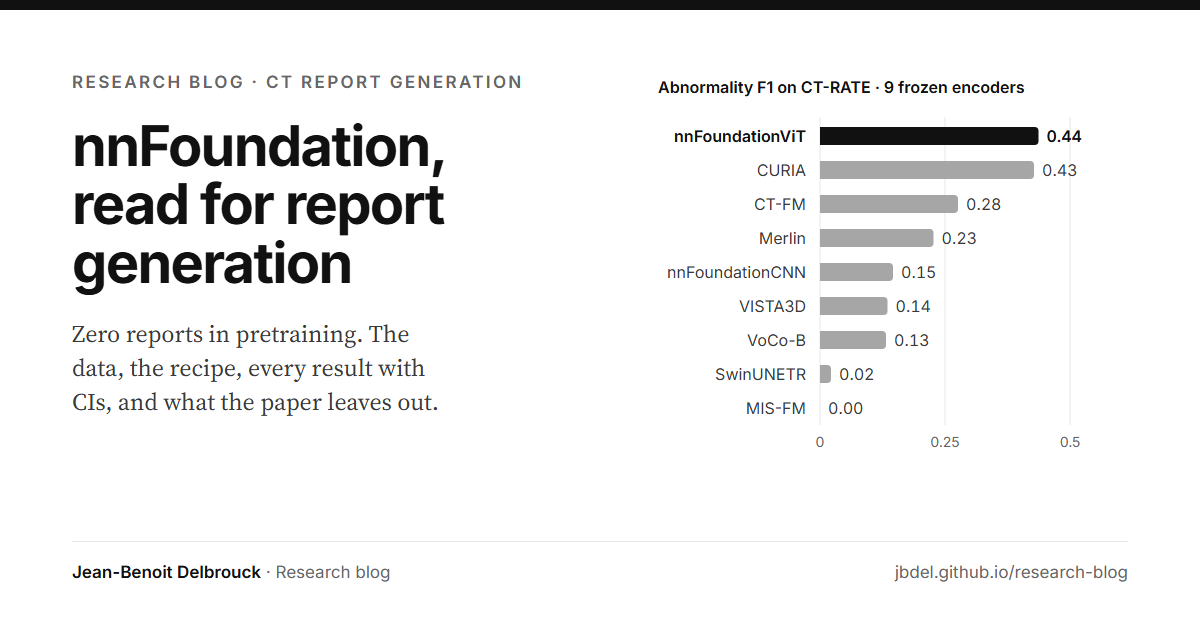
The report-generation side of DKFZ’s 2.16M-volume radiology foundation model: where the data came from, how a 674M 3D ViT was pretrained without a single report, how it was wired into Qwen2.5-VL-3B, and what the appendix numbers show.

CT report generationNature 2026Main2 Oct 2026~11 min read

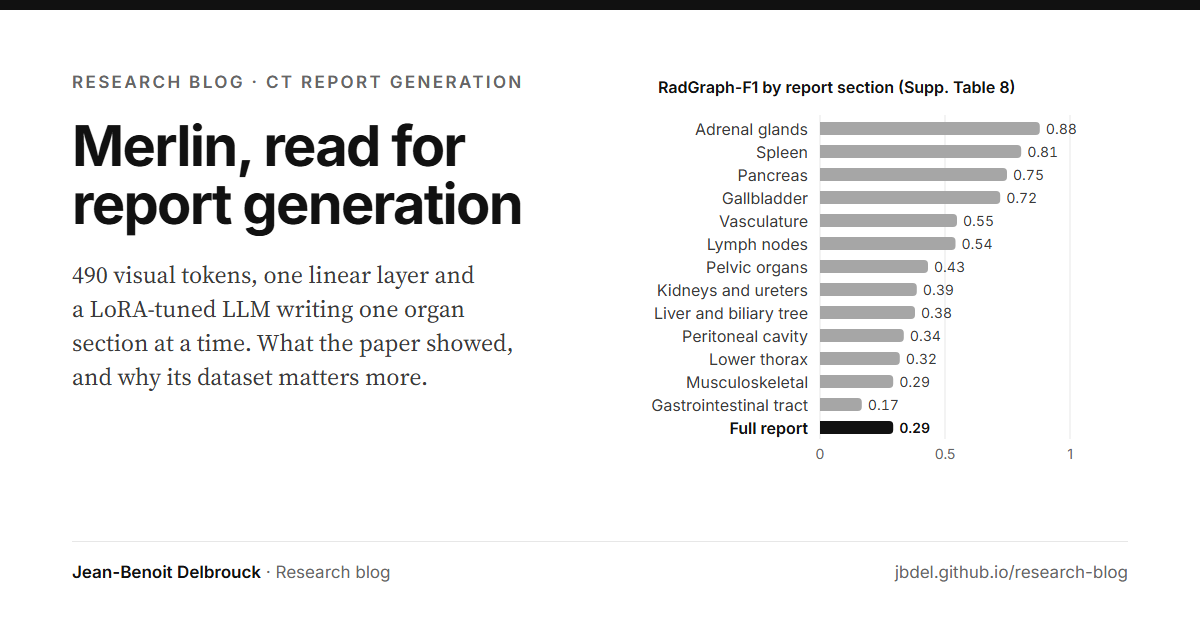
Merlin, read for report generation

The report-generation side of Merlin, the abdominal CT foundation model published in Nature: 490 visual tokens, one linear adapter and a LoRA-tuned language model writing one organ section at a time, what the scores show, and why the released dataset matters more.

Report-generation evaluationMICCAI 2025Main6 Oct 2026~8 min read

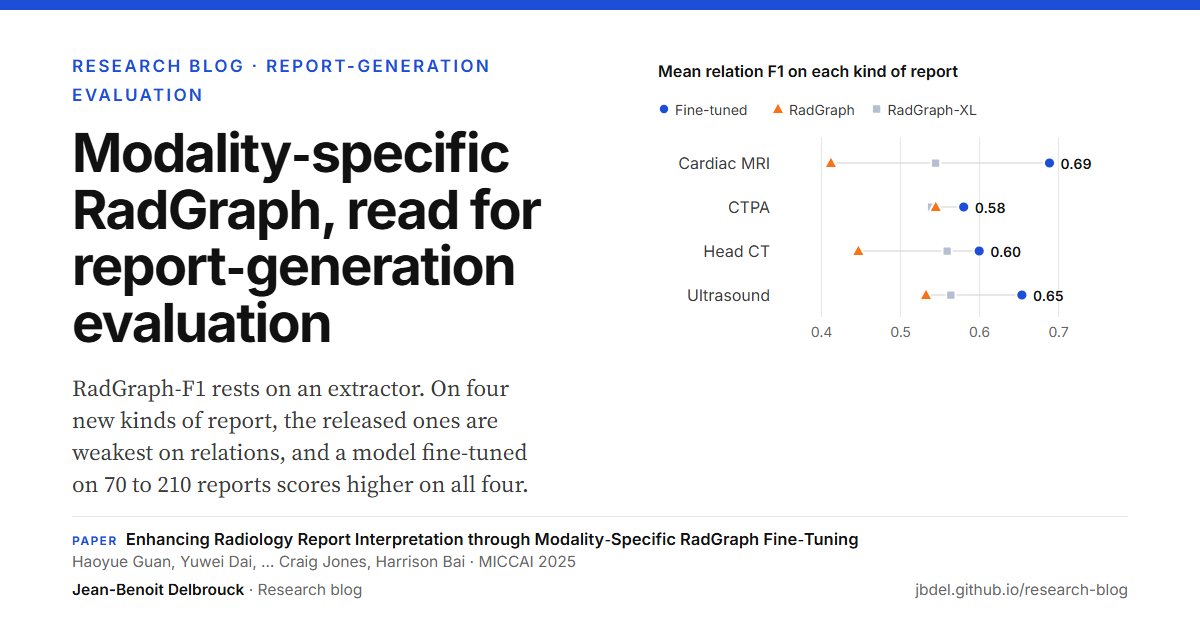
Modality-specific RadGraph, read for report-generation evaluation

A MICCAI 2025 paper labels 800 cardiac MRI, CTPA, head CT and ultrasound reports and tests the released RadGraph extractors on them. What a fine-tuned extractor gains, what the comparison can and can't say, and what it means for scoring CT and MRI reports with RadGraph-F1.

Chest X-ray report generationMICCAI 2025Main6 Oct 2026~8 min read

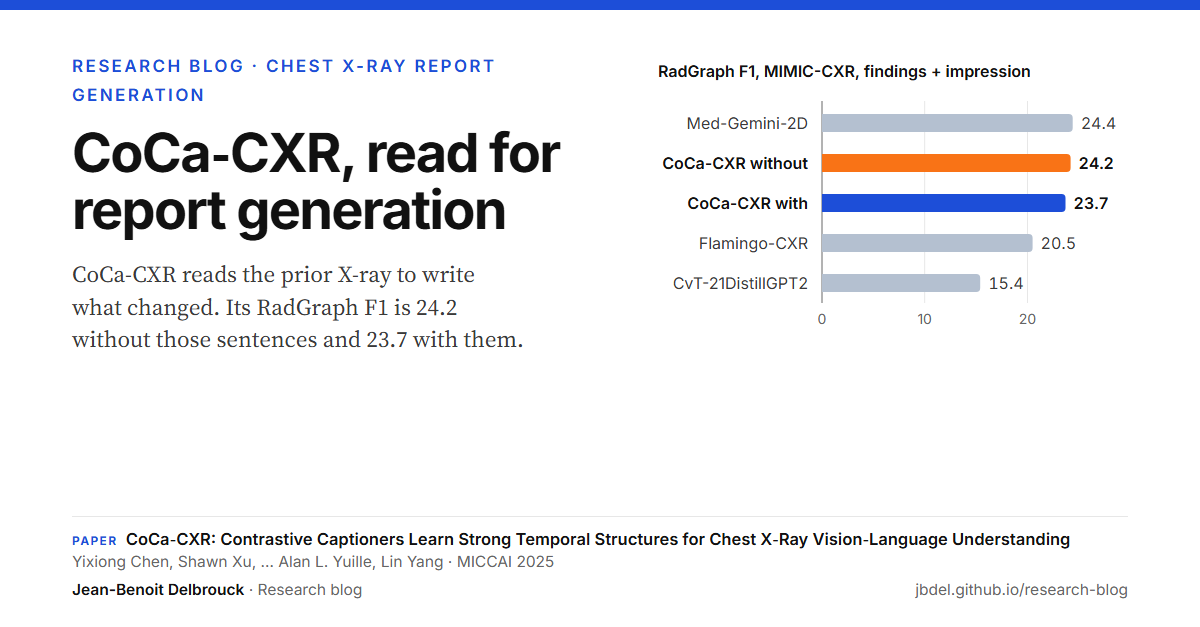
CoCa-CXR, read for report generation

CoCa-CXR is built to write what changed since the last chest X-ray, yet its RadGraph F1 is no higher with those comparison sentences. What its report score, its copied baselines and its progression benchmark can and can't show.

CT report generationMICCAI 2025Main6 Oct 2026~8 min read

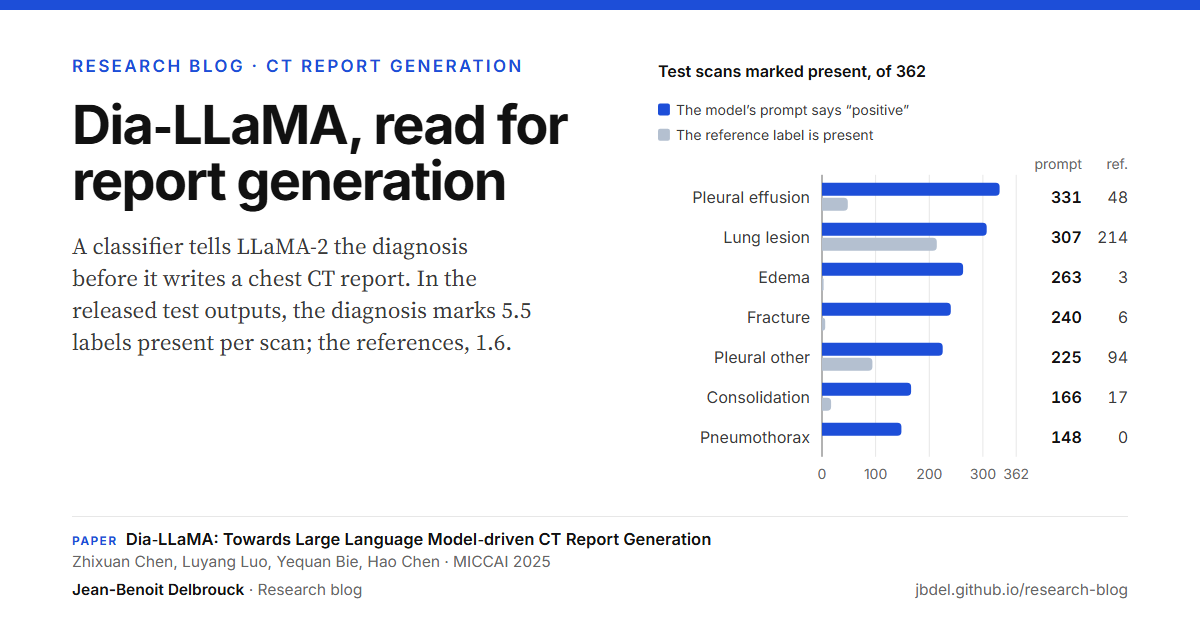
Dia-LLaMA, read for report generation

Dia-LLaMA writes a classifier's verdict into the prompt of a LoRA-tuned LLaMA-2 that reports chest CT. The paper's gain is 0.027 F1 on 362 test scans; what the prompt says in the outputs released with the code, how much of it reaches the report, and what a fixed answer scores on the same rulers.

Chest X-ray report generationMICCAI 2025Main6 Oct 2026~8 min read

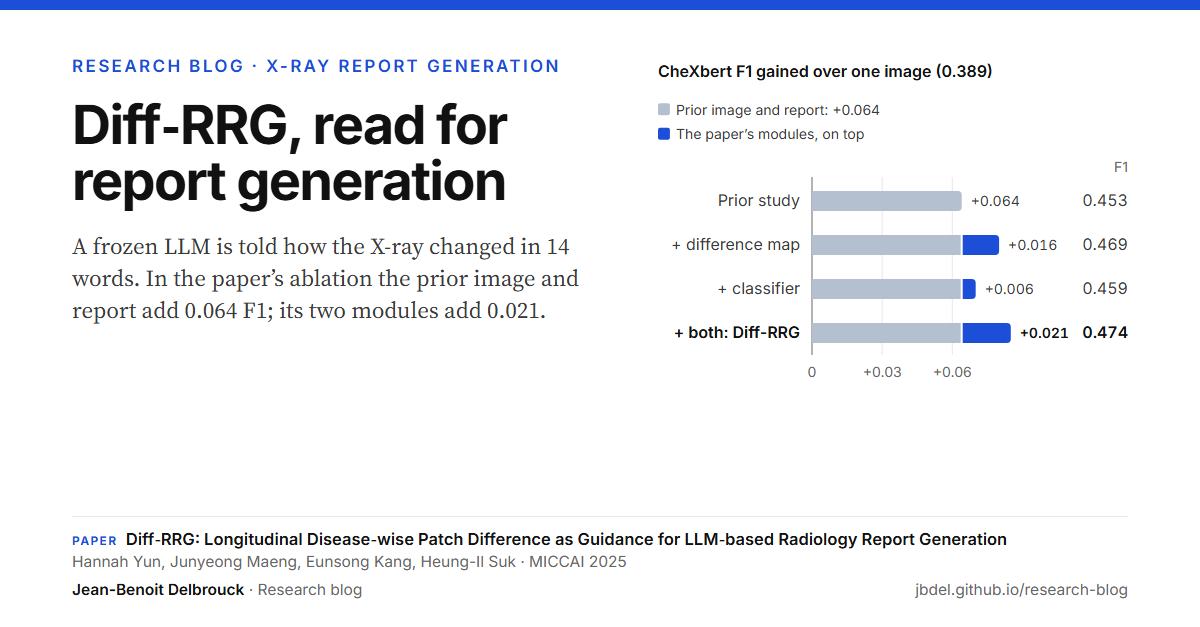
Diff-RRG, read for report generation

Diff-RRG turns the prior chest X-ray into fourteen status words for a frozen LLM. Most of its gain comes from adding the prior study at all; what its two modules add, what the comparison with the closest baseline rests on, and what the released code does.

Pathology report generationMICCAI 2025Main6 Oct 2026~8 min read

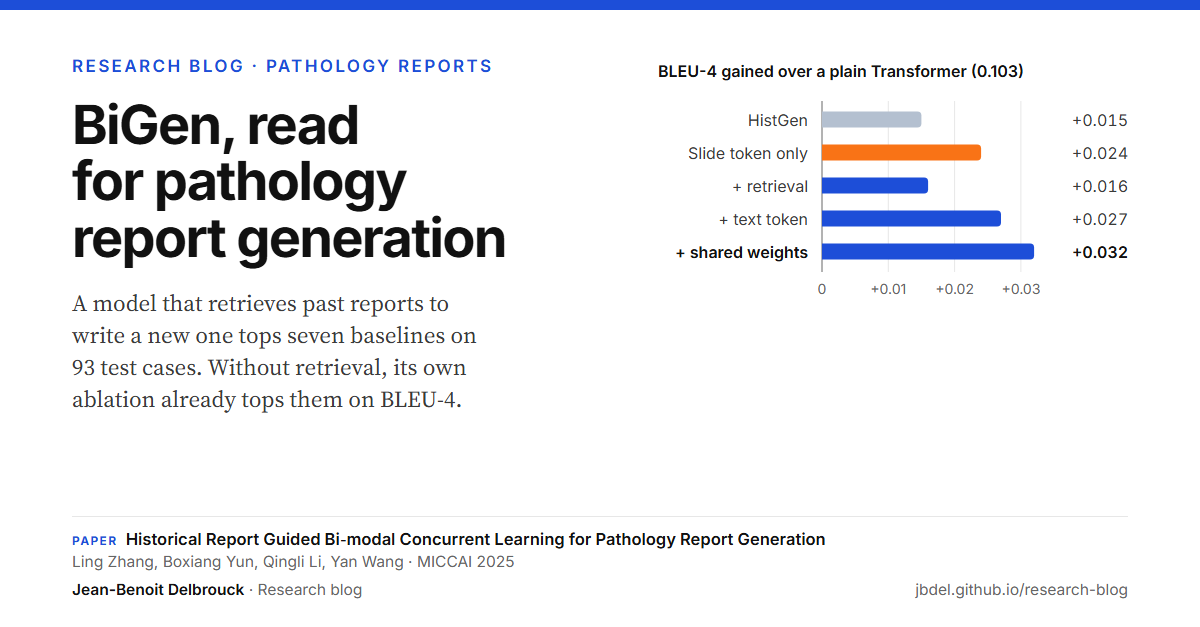
BiGen, read for pathology report generation

BiGen retrieves sentences from past reports to write a breast pathology report from a whole-slide image, and leads every column of its benchmark on 93 test reports. What its own ablation says about where the gain comes from, and what word-overlap scores can't see.

Report-generation evaluationMICCAI 2025Main5 Oct 2026~8 min read

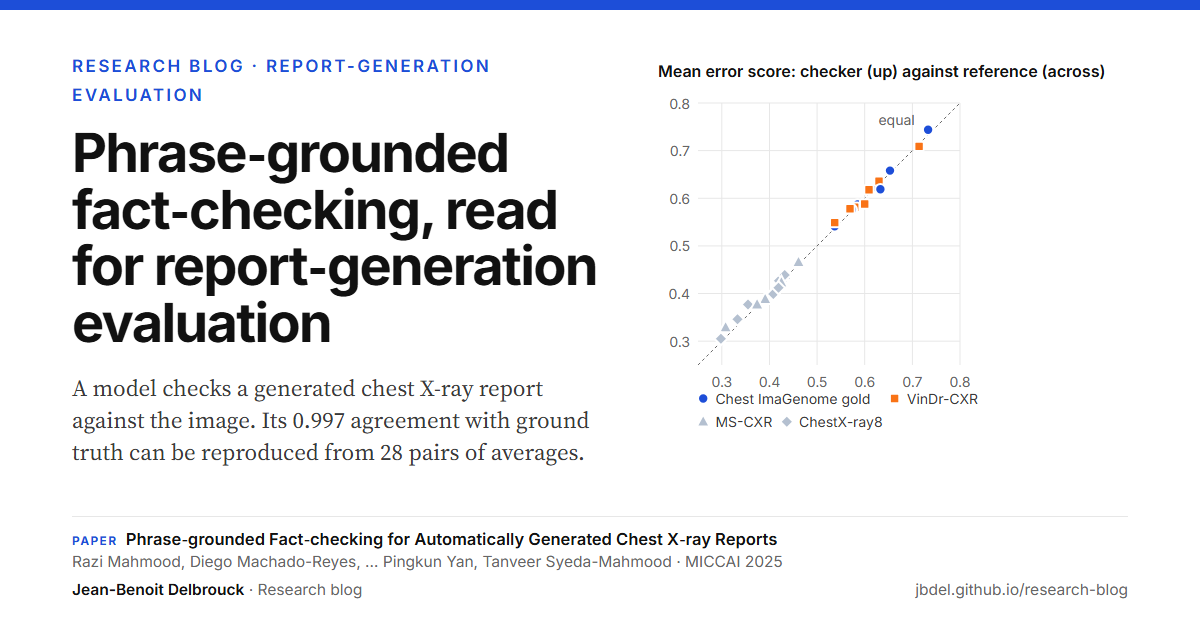
Phrase-grounded fact-checking, read for report-generation evaluation

A model checks a generated chest X-ray report against the image itself: for each finding it answers real or fake and draws a box, with no reference report. Its headline number, a concordance of 0.997 with ground truth, can be reproduced from 28 pairs of averages in one table: what that shows, and what it leaves open.

CT report generationMICCAI 2025Main5 Oct 2026~8 min read

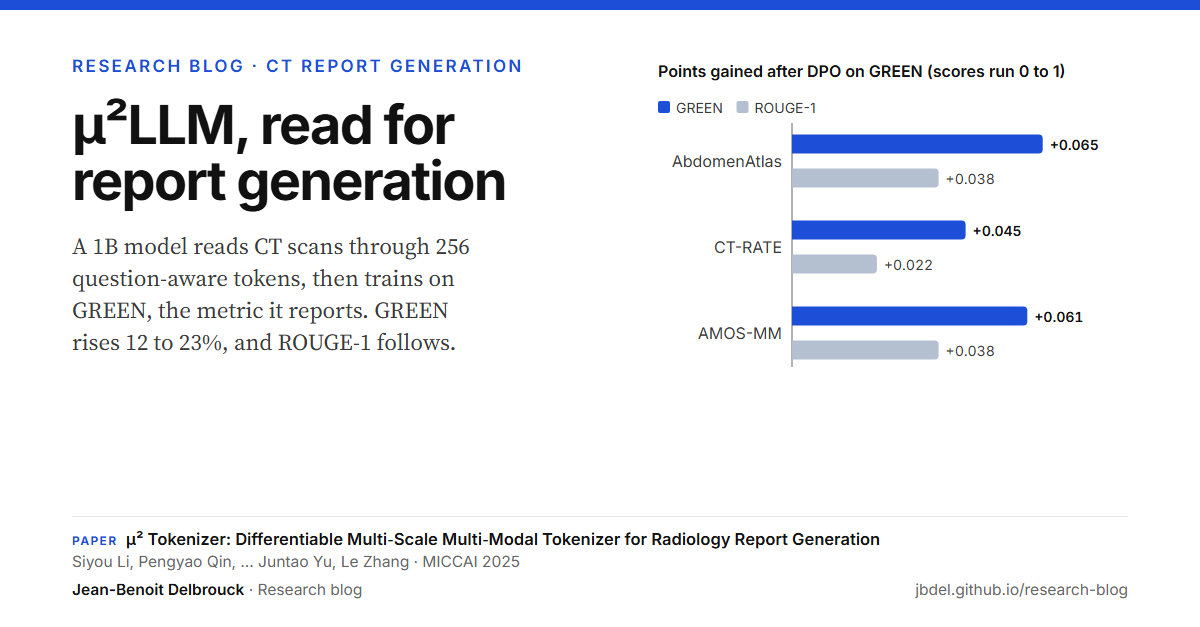
µ²LLM, read for report generation

µ²LLM puts a question-aware bottleneck between a 3D image encoder and a 1B language model, then tunes it by direct preference optimisation towards GREEN, the metric it reports. What each step adds on three CT report datasets, and what the comparison with larger models rests on.

MRI report generationMICCAI 2025Main5 Oct 2026~8 min read

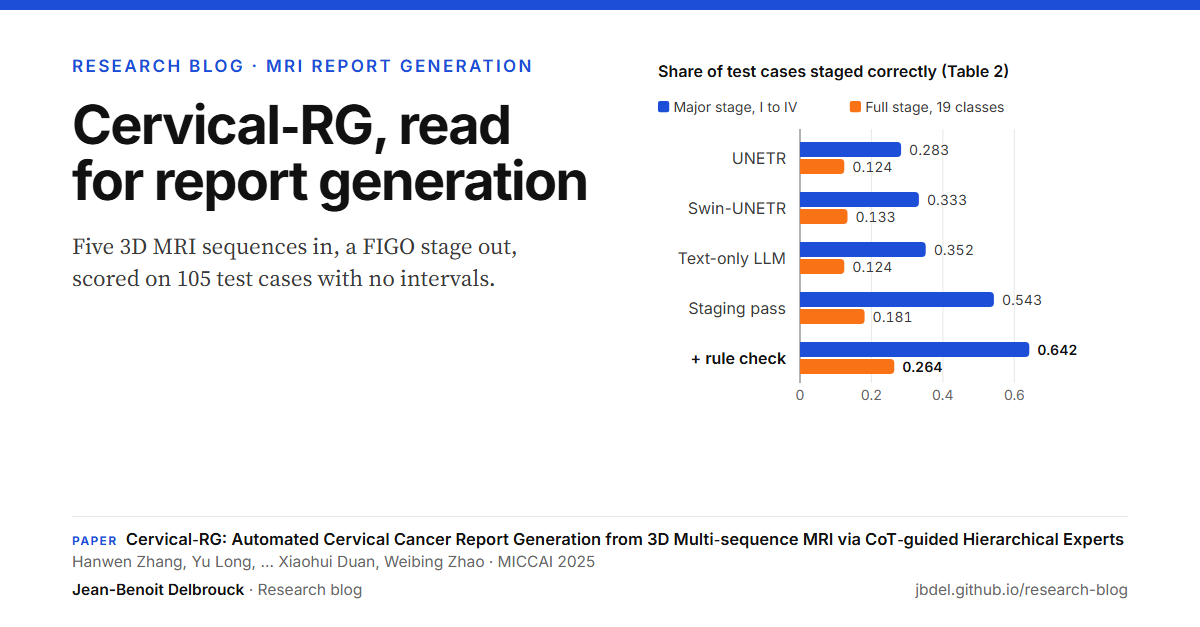
Cervical-RG, read for report generation

Cervical-RG writes a cervical-cancer MRI report from five 3D sequences and ends it on a FIGO stage, in three passes. What its 105 test cases can carry: a findings text slightly ahead of the same language model fed 2D slices, and a stage that is right for 64% of cases, 26% with the substage.

Chest X-ray report generationMICCAI 2025Main5 Oct 2026~8 min read

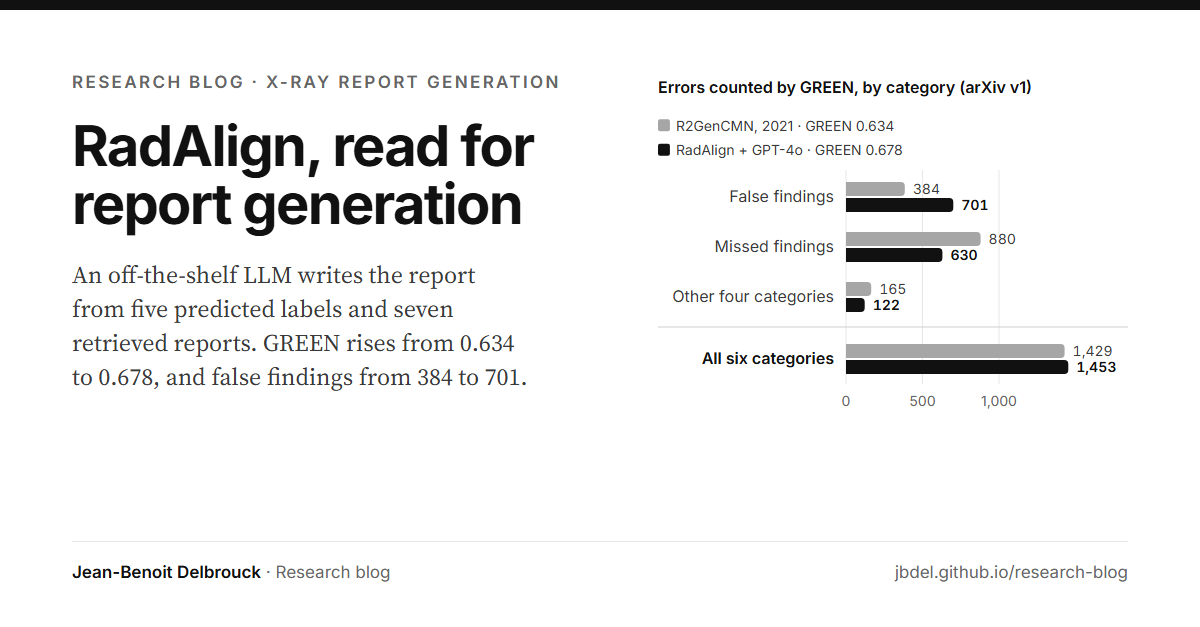
RadAlign, read for report generation

RadAlign trains a small classifier, then lets an off-the-shelf LLM write the chest X-ray report from its predictions and seven retrieved reports. What the LLM is told about the image, and what the GREEN gain over a 2021 baseline is made of.

PET/CT report generationMICCAI 2025Main5 Oct 2026~8 min read

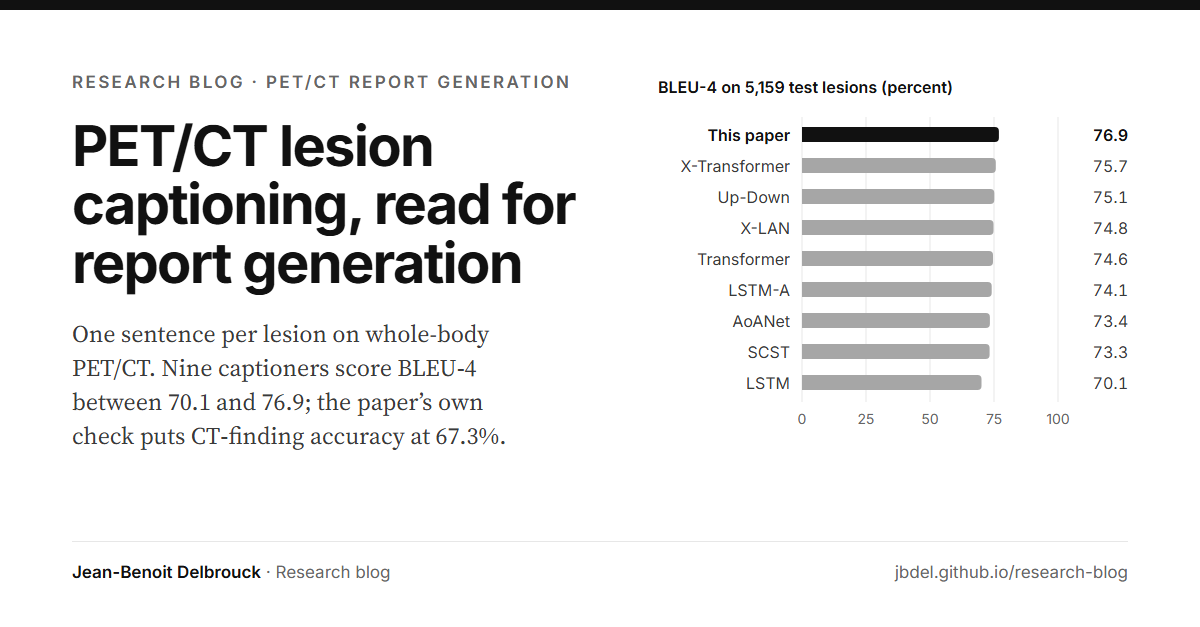
PET/CT lesion captioning, read for report generation

A model writes one sentence per lesion on whole-body PET/CT, guided by a predicted anatomical location. Its captions reach a BLEU-4 of 76.9 while its own word-matching check puts CT-finding accuracy at 67.3%: a lesson in how to score lesion-level reports.

Pathology report generationMICCAI 2025Main5 Oct 2026~8 min read

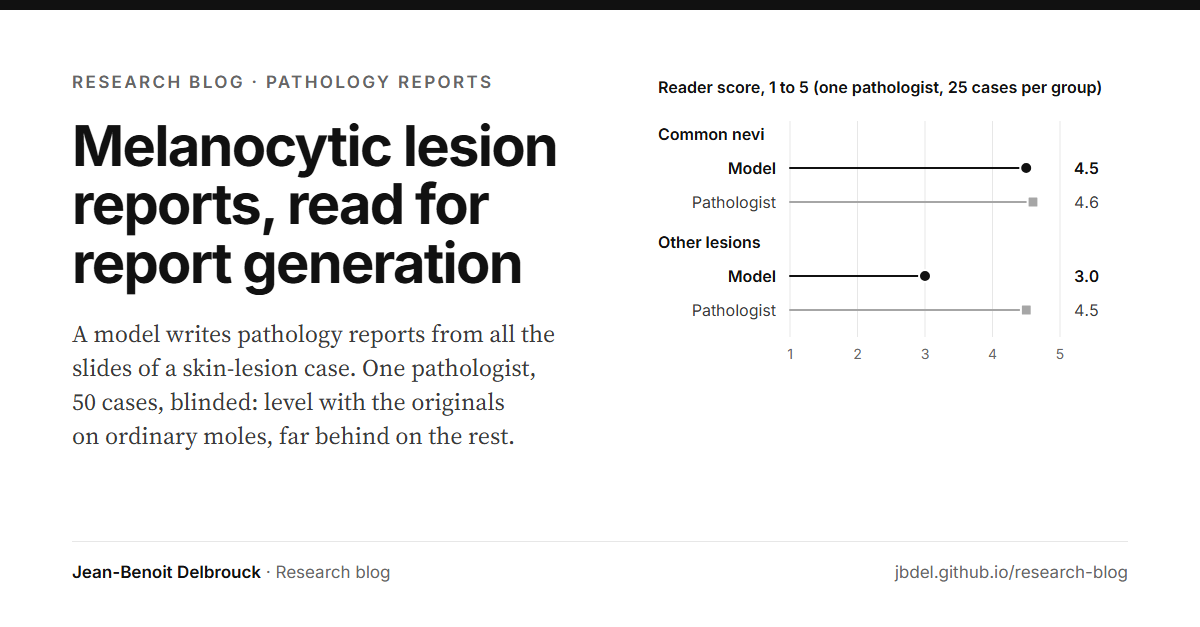
Melanocytic lesion reports, read for report generation

A small vision–language model writes pathology reports for melanocytic skin lesions, and one pathologist scores 50 of them blind against the originals: level on ordinary moles, far behind on the other lesions. How far that evidence goes.

Report-generation evaluationMICCAI 2025Main5 Oct 2026~8 min read

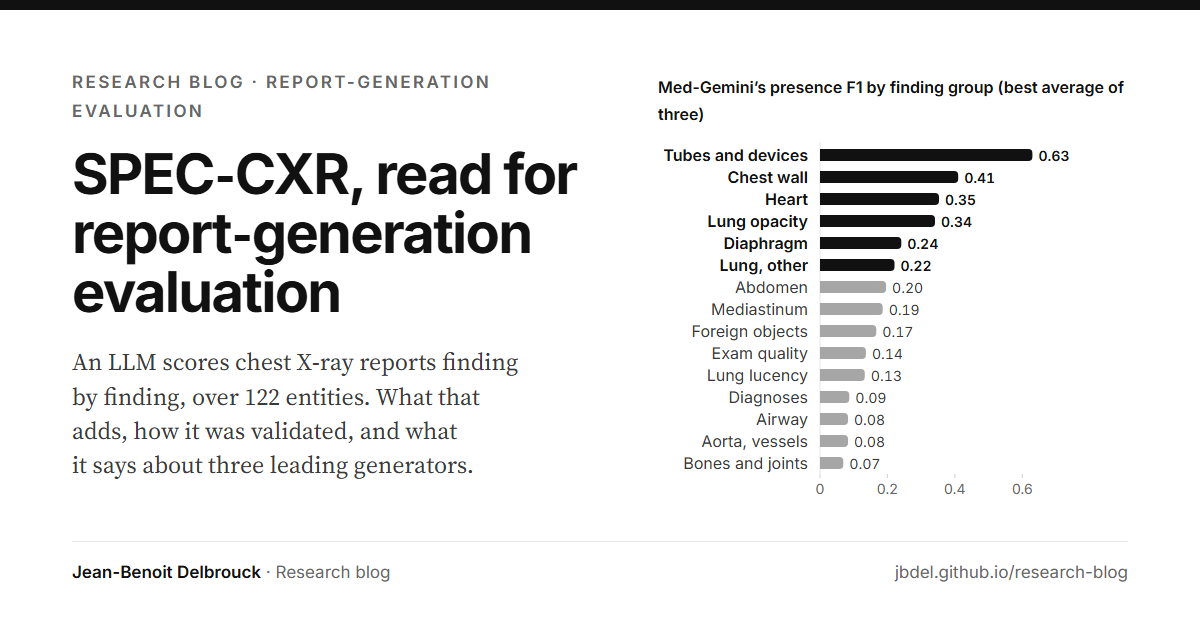
SPEC-CXR, read for report-generation evaluation

SPEC-CXR scores a generated chest X-ray report finding by finding, over 122 fixed entities. What that adds to report-level metrics, how the scorer was validated, and what it says about three leading generators.

CT report generationMICCAI 2025Main5 Oct 2026~8 min read

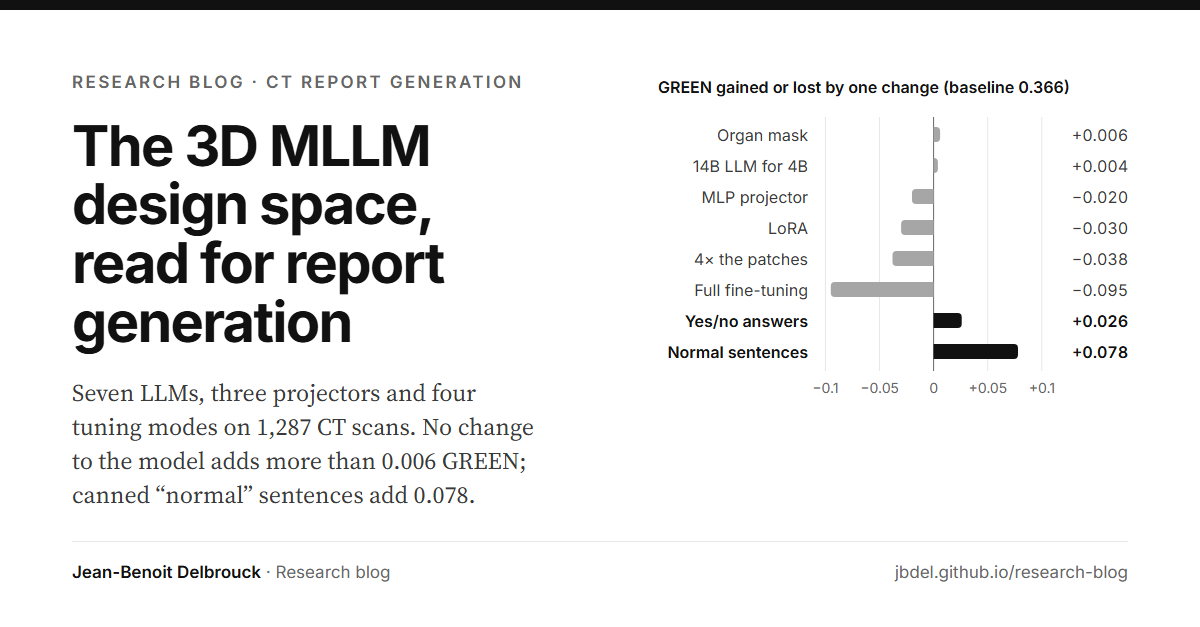
The 3D MLLM design space, read for report generation

A MICCAI 2025 study swaps the LLM, the projector, the tuning method and the input size of a 3D CT report generator trained on 1,287 scans. No change to the model adds more than 0.006 GREEN, while canned “normal” sentences add 0.078. What that says about small-data training, and about the metric.